Claude Fable 5.2 directs Blender to build a warship, next to GPT-6 Astra and Gemini 4 Argon
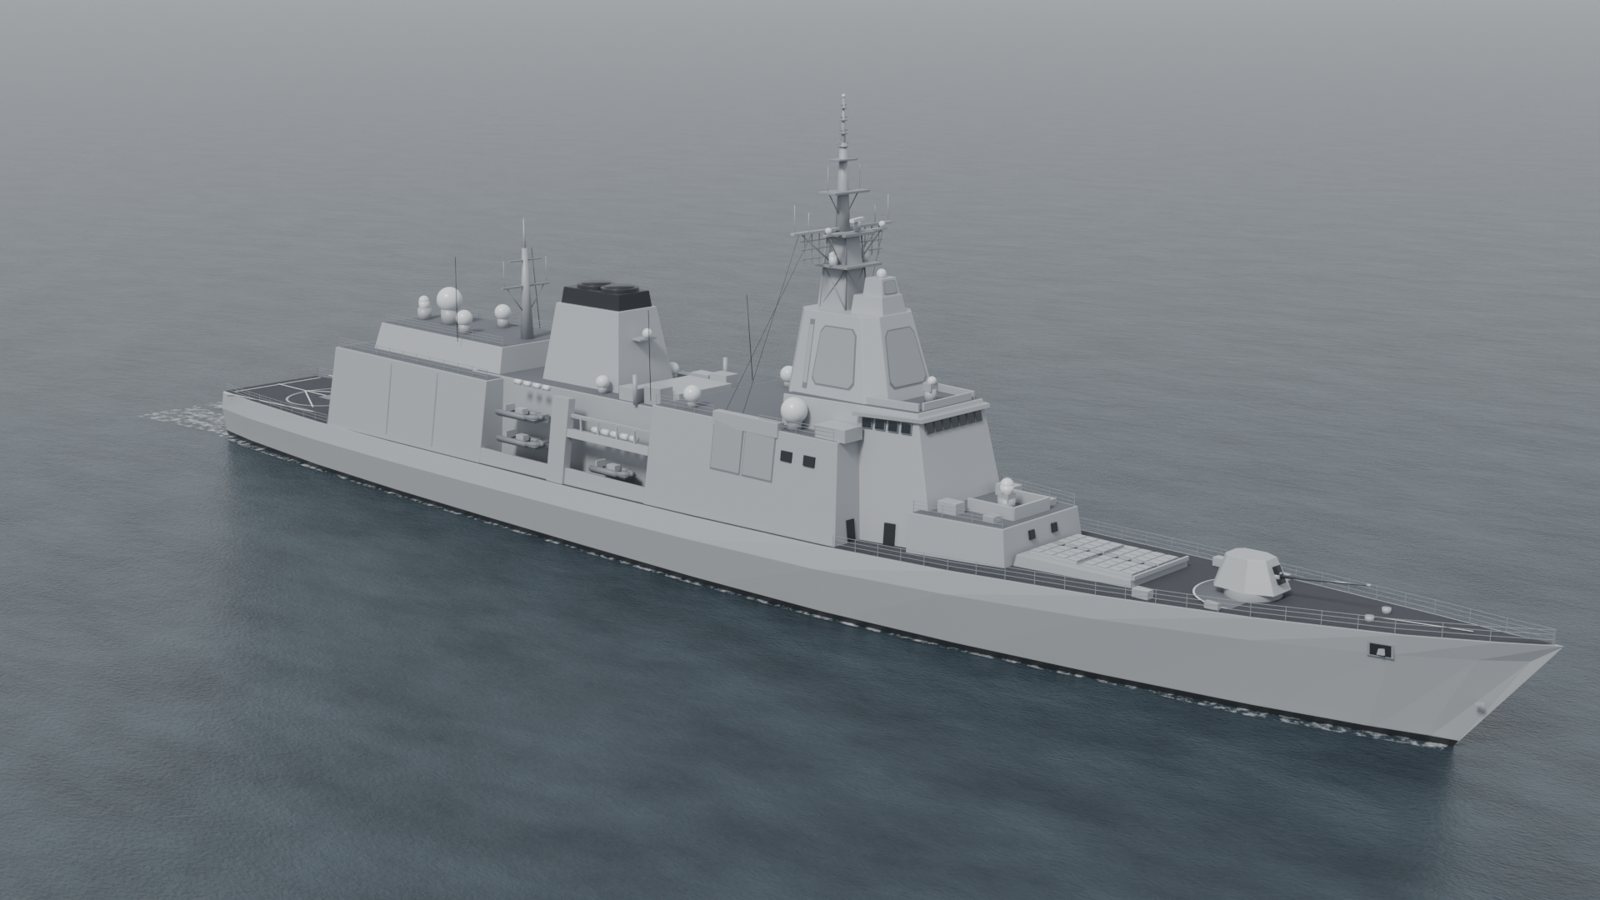
On 14 October we gave GPT-6 Astra and Gemini 4 Argon one picture of a warship and the same short prompt: write Blender Python, render, look at your own render, fix it, repeat until it matches. Today the newest Claude model, Fable 5.2, gets the exact same picture and prompt at three effort levels. Time, tokens and API price are logged for every run, and every ship is a 3D model you can spin.
The three runs
All three runs are done. Results below.
Effort: lowwaiting
Effort: mediumwaiting
Effort: highwaiting
What we saw
- Fable 5.2 finished all three runs on its own, with no stuck requests: 7.3 minutes for $2.14 at low, 12.3 minutes for $2.80 at medium, 32.6 minutes for $12.32 at high.
- Low and medium cost about what Astra's did ($2.70 and $2.74). Low was the fastest run on this page that finished on its own (Astra 10.9 minutes, Gemini 4 in Antigravity 24). At medium, Astra was a minute quicker (11.4 against 12.3).
- High is where the bill jumps: $12.32, about 2.3 times Astra's $5.24 and more than twice Gemini 4's $5.2 to $5.4. Fable wrote 175k output tokens (Astra: 32k) over 37 model calls, and re-read 5.9 million cached input tokens along the way. Most of that price is output and cache writes.
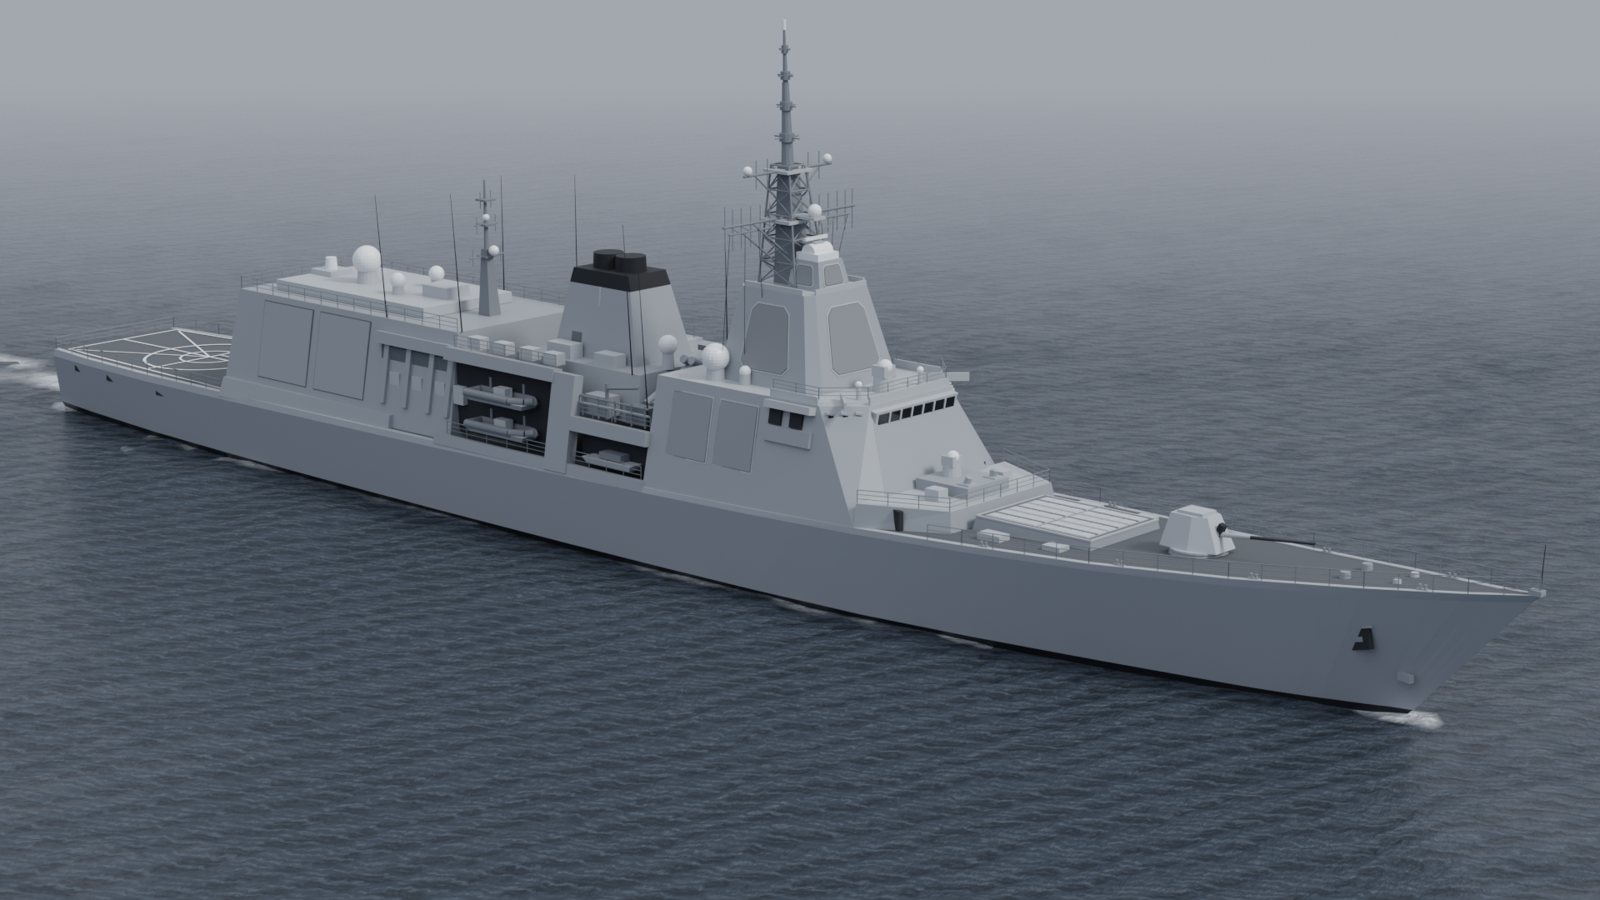
- The ships are light and well split: 21k to 35k triangles in 23 to 89 named parts. Astra's ships have 52k to 156k triangles; Gemini 4 merges its ship into 8 to 17 parts.
- Which ship looks best is your call. All three Fable ships show the whole hull with the helicopter deck, mast, stack, deck gun and missile cells; spin them against the others below. One flag from our automatic framing check: the ship fills 98 to 100% of the picture width in all three Fable renders, which it counts as touching the frame edge (Astra's high render passed).
Results
| Effort | Model | Time | API price | Input tokens | Output tokens | Triangles | Parts | What happened |
|---|---|---|---|---|---|---|---|---|
| low | Claude Fable 5.2 | 7.3 min | $2.14 | 399,605 | 29,144 | 23,736 | 89 | Finished on its own |
| low | GPT-6 Astra | 10.9 min | $2.70 | 1,579,727 | 13,593 | 51,666 | 1129 | Finished on its own |
| low | Gemini 4 Argon · Antigravity CLI | 24 min | $2.80 | 3,553,754 | 98,567 | 60,992 | 8 | Finished on its own |
| low | Gemini 4 Argon · Claude Code | 6.4 min | $1.48 | 1,336,388 | 77,662 | 13,476 | 17 | Model ready at 6.4 min, then a request hung; stopped at 50 min |
| medium | Claude Fable 5.2 | 12.3 min | $2.80 | 465,565 | 40,700 | 21,145 | 23 | Finished on its own |
| medium | GPT-6 Astra | 11.4 min | $2.74 | 1,463,536 | 14,592 | 75,872 | 1512 | Finished on its own |
| medium | Gemini 4 Argon · Antigravity CLI | 38 min | $3.05 | 3,777,691 | 149,065 | 23,266 | 12 | Finished on its own |
| medium | Gemini 4 Argon · Claude Code | no model | $1.42 | 794,081 | 86,689 | none | A request hung before it saved a model; stopped at 50 min | |
| high | Claude Fable 5.2 | 32.6 min | $12.32 | 6,139,933 | 175,110 | 35,222 | 34 | Finished on its own |
| high | GPT-6 Astra | 18.5 min | $5.24 | 2,824,693 | 31,585 | 155,834 | 156 | Finished on its own |
| high | Gemini 4 Argon · Antigravity CLI | 40 min | $5.36 | 5,059,531 | 267,500 | 31,545 | 11 | Finished on its own |
| high | Gemini 4 Argon · Claude Code | 32.8 min | $5.21 | 3,600,859 | 349,371 | 61,572 | 12 | Finished on its own |
API price = tokens times list price per million tokens. Claude Fable 5.2: $8 input, $0.20 cached input, $10 or $16 to write the cache (5 minutes or 1 hour; Claude Code uses 1 hour), $40 output; we ran it on a Claude subscription, so for us this is an equivalent, not a bill. GPT-6 Astra: $10 input, $1 cached input, $50 output (ChatGPT subscription, also an equivalent). Gemini 4 Argon: $2 input, $0.20 cached input, $10 output. Input tokens include cached ones. The Astra and Gemini 4 rows are the 14 October runs, not rerun.
The picture and the prompt
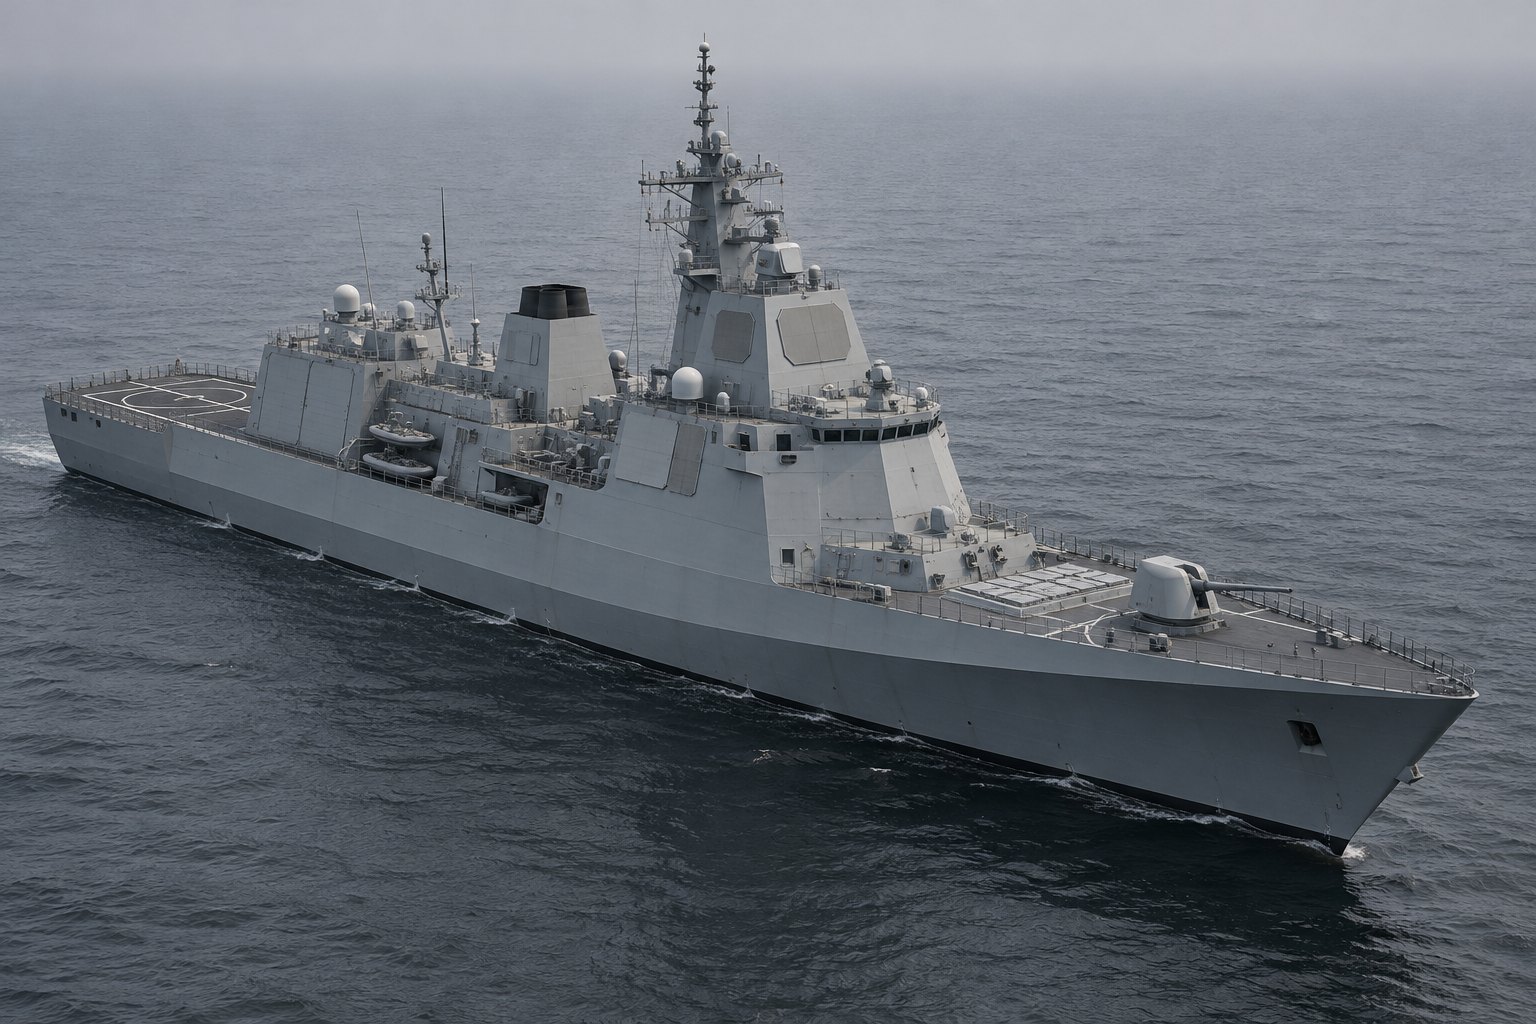
All models got this picture and this prompt, word for word (machine names replaced):
Recreate the warship in the reference image as a 3D model in Blender.
The reference is reference.jpeg in this directory: look at it with your image tool first.
Blender 5.2 is headless on another machine (it has an NVIDIA GPU; Cycles can use OPTIX). Write bpy scripts here, run them with:
  ssh <gpu-box> blender -b --python-exit-code 1 --python <remote-dir>/<script>.py
(scp your script to <gpu-box>:<remote-dir>/ first, scp renders back here, then LOOK at them with your image tool.)
Iterate until the render matches the reference: hull shape and bow, superstructure blocks and radar panels, mast, stack, deck gun, missile cells, flight deck and hangar, haze-grey paint.
Real-world scale in metres, separate named objects for the main parts.
Deliver in this directory: final.png (1920x1080 Cycles, similar 3/4 view) and cruiser.glb. Stop when you judge it matches.
Side by side, effort by effort
Left to right: Claude Fable 5.2, GPT-6 Astra, Gemini 4 Argon in Google's Antigravity CLI. Drag to turn a ship, scroll or pinch to zoom, right-drag to pan. Full screen shows the most detail. Under each viewer is the model's own Cycles render.
Effort: low
same picture, same promptClaude Fable 5.2
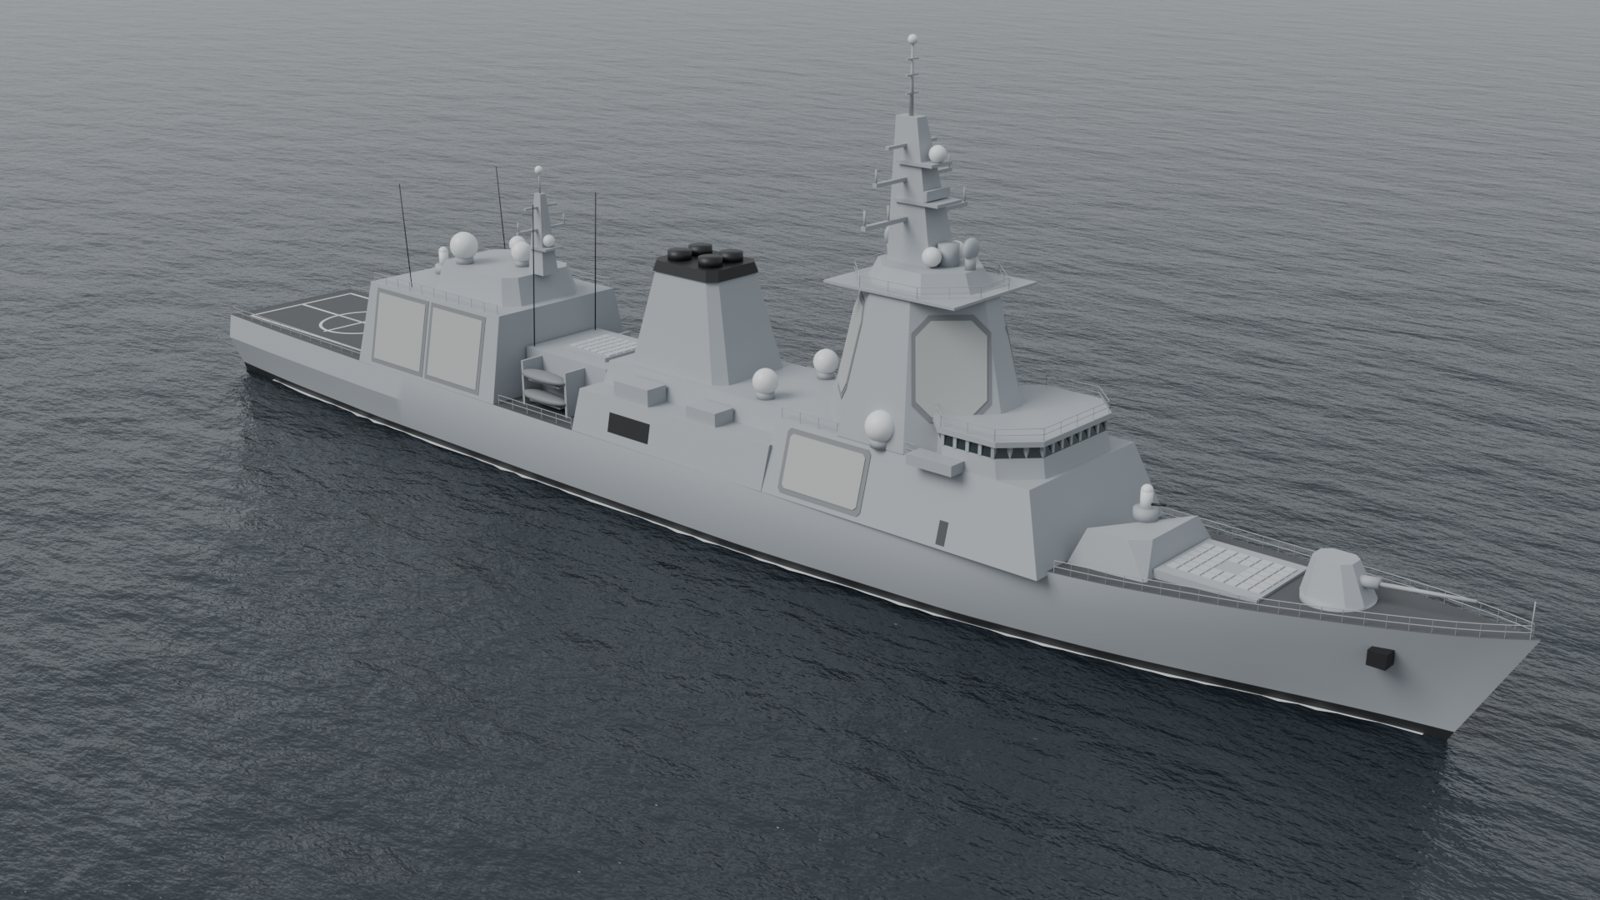
GPT-6 Astra
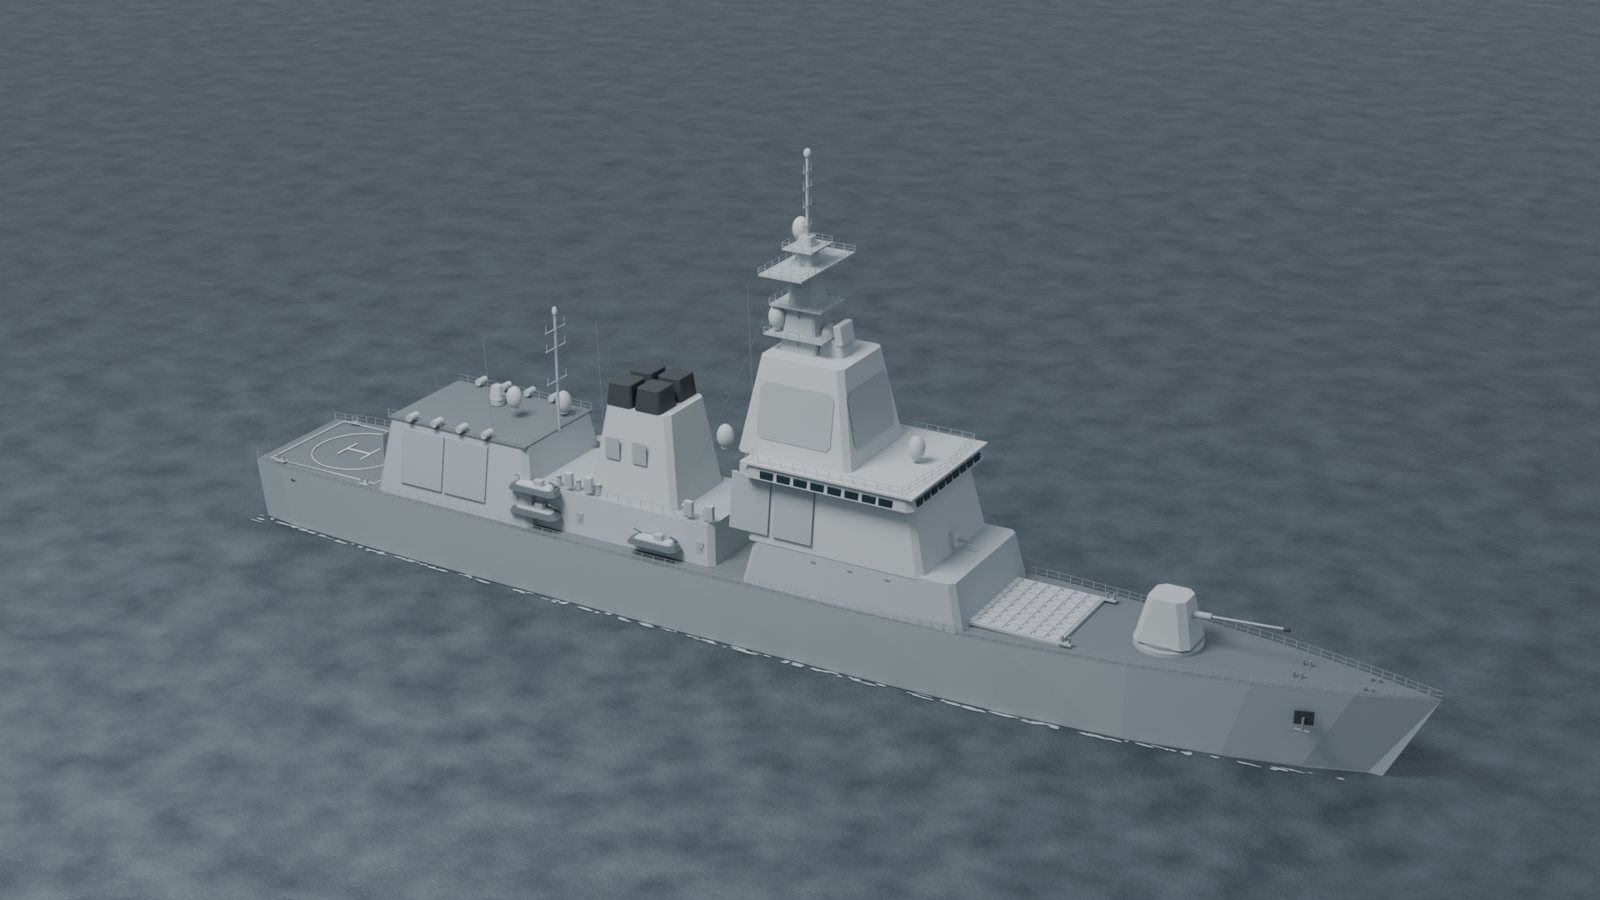
Gemini 4 Argon · Antigravity CLI
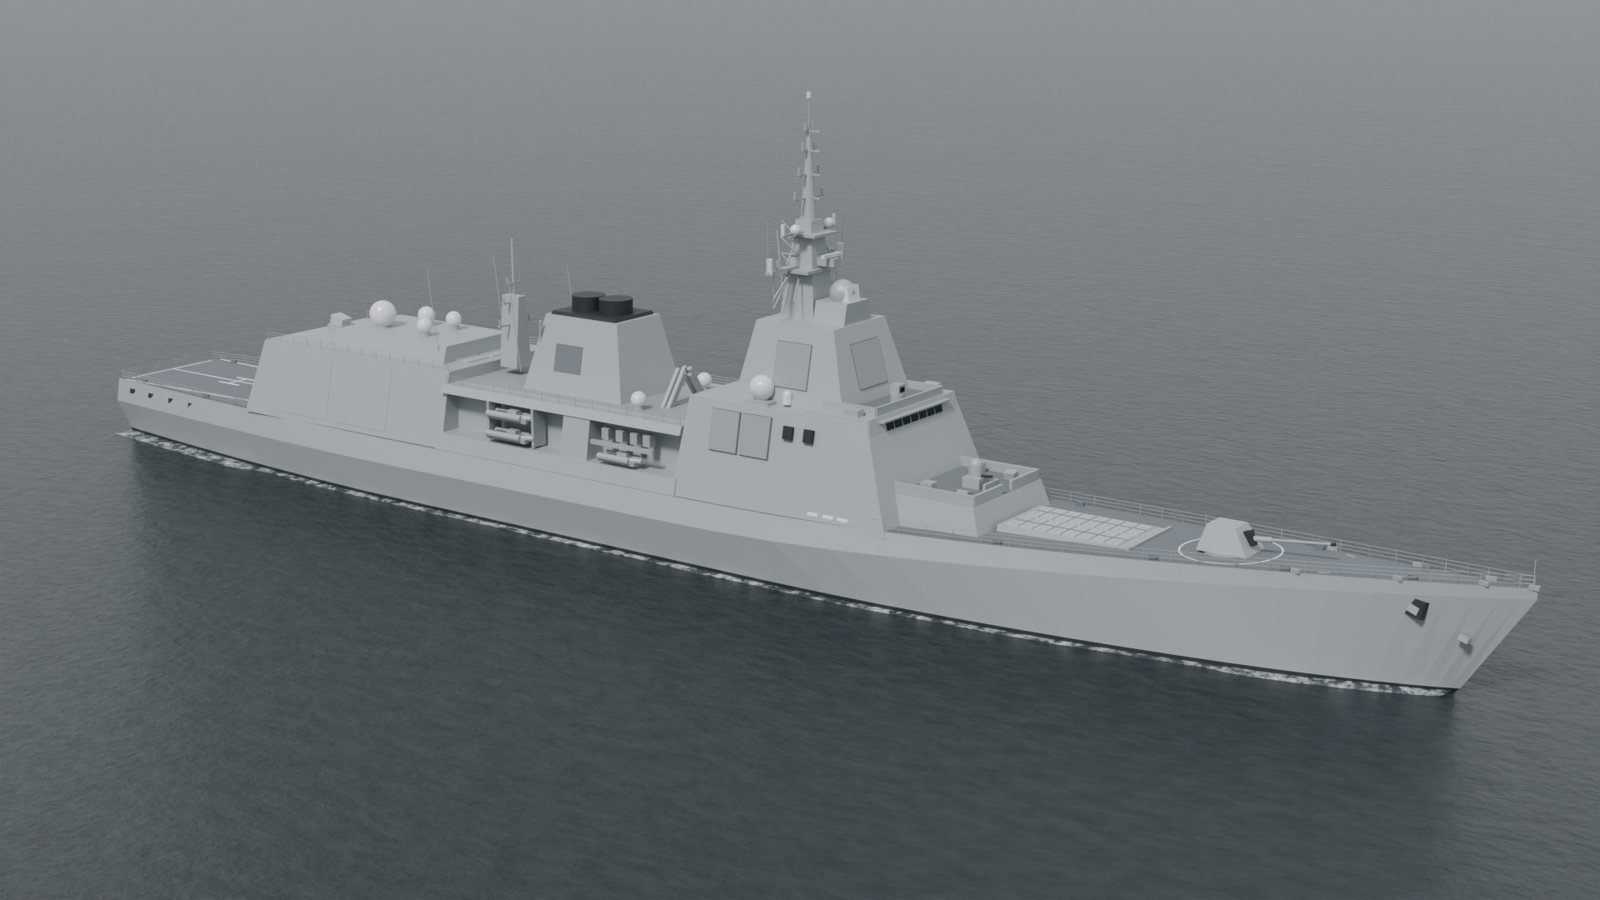
Effort: medium
same picture, same promptClaude Fable 5.2
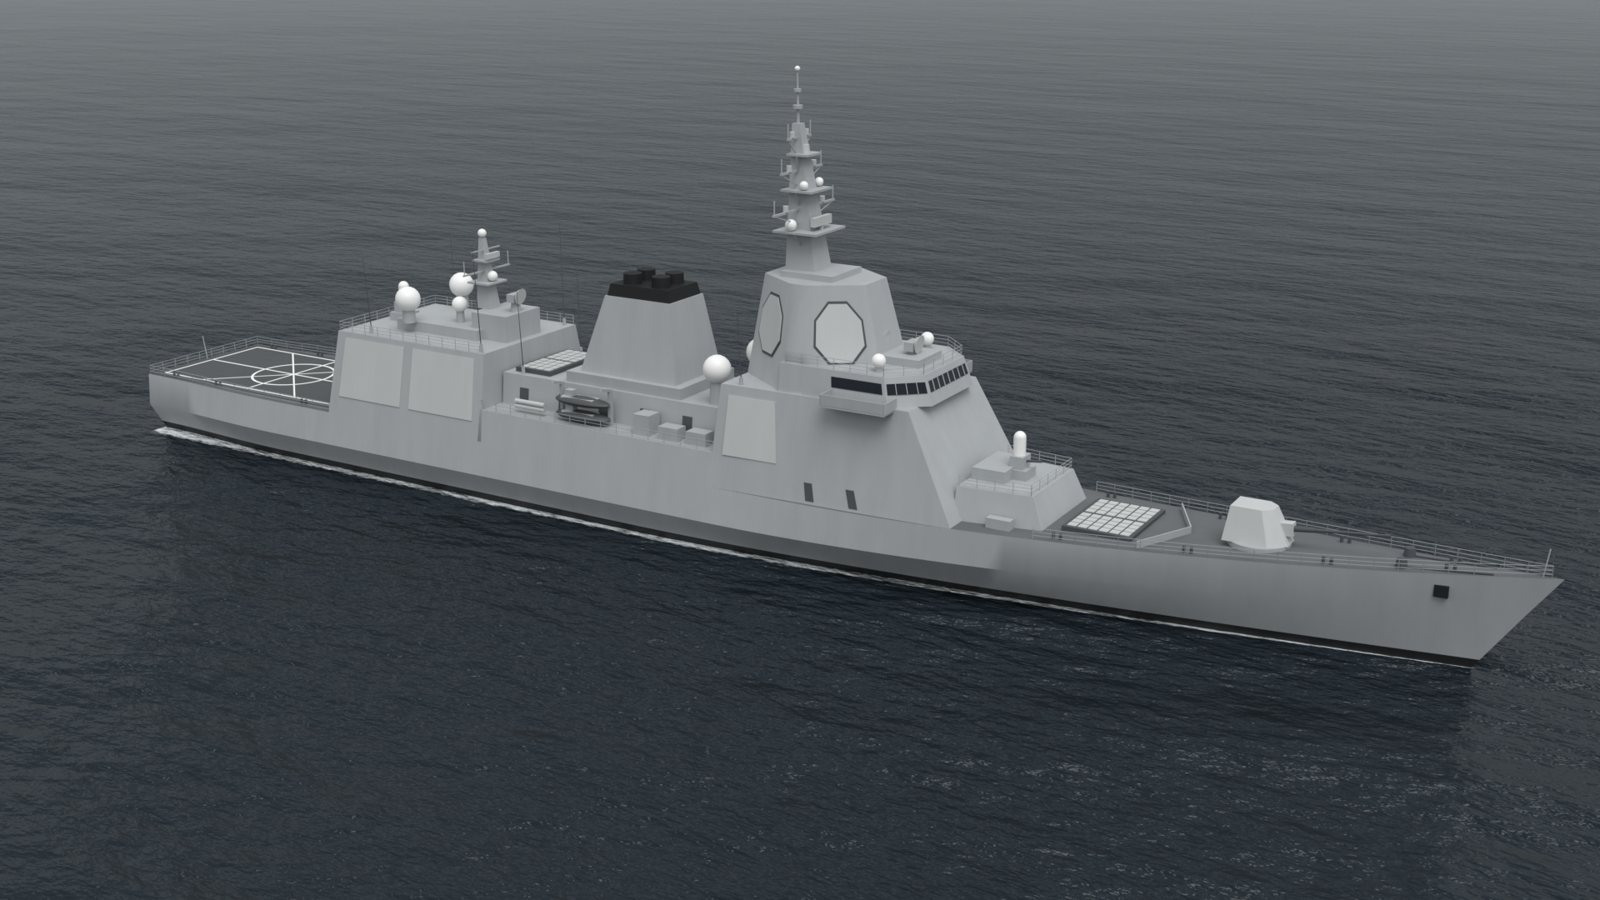
GPT-6 Astra
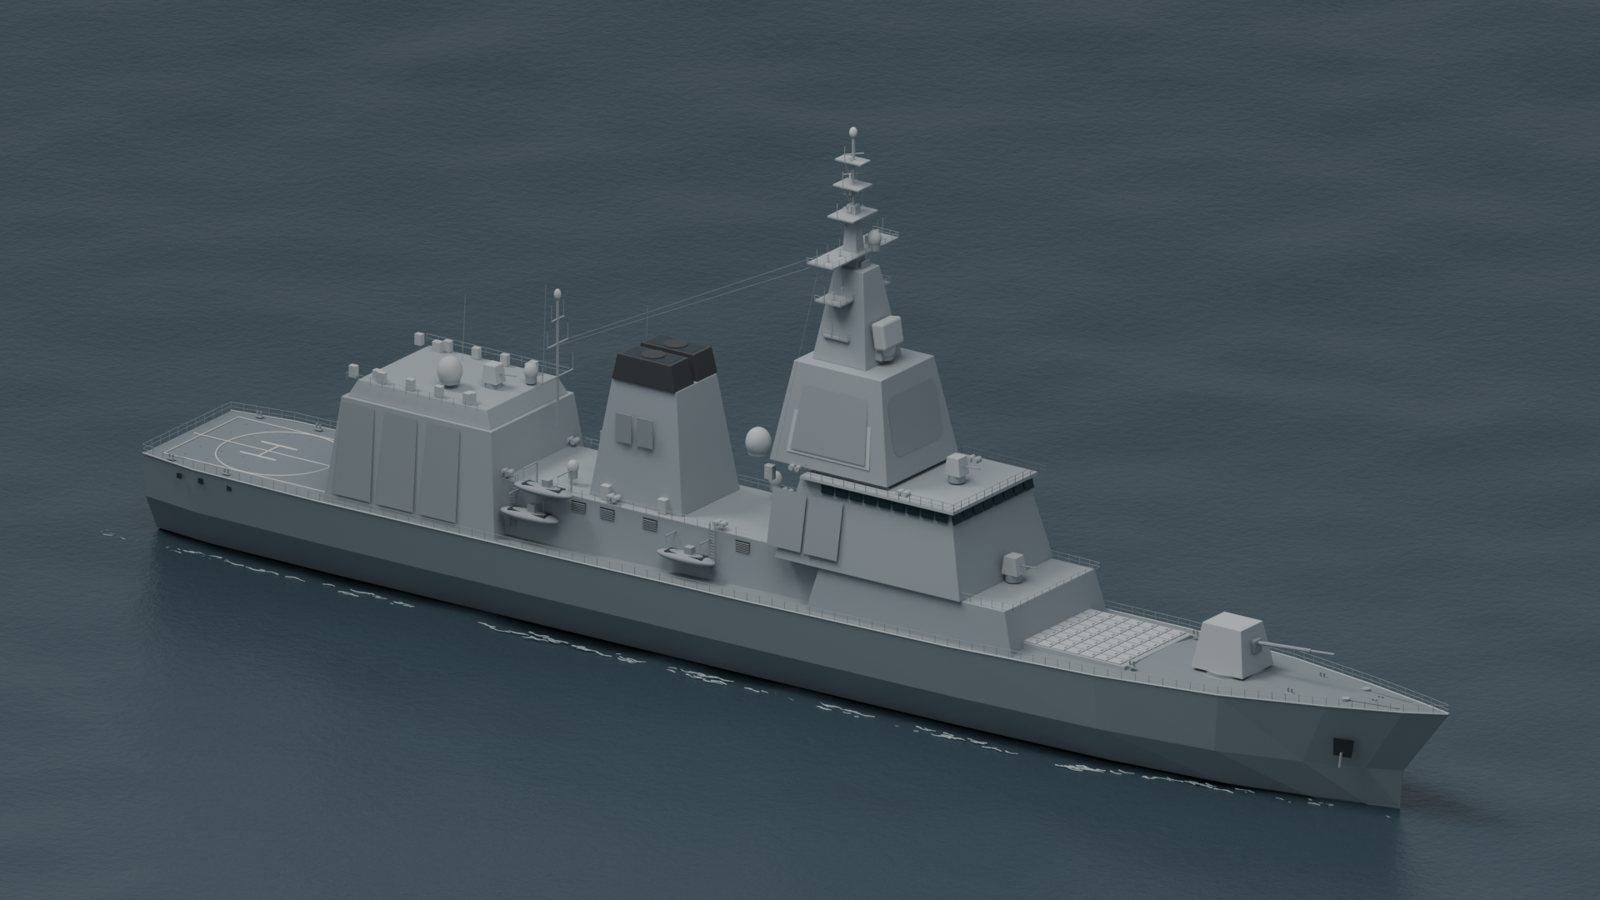
Gemini 4 Argon · Antigravity CLI
Effort: high
same picture, same promptClaude Fable 5.2
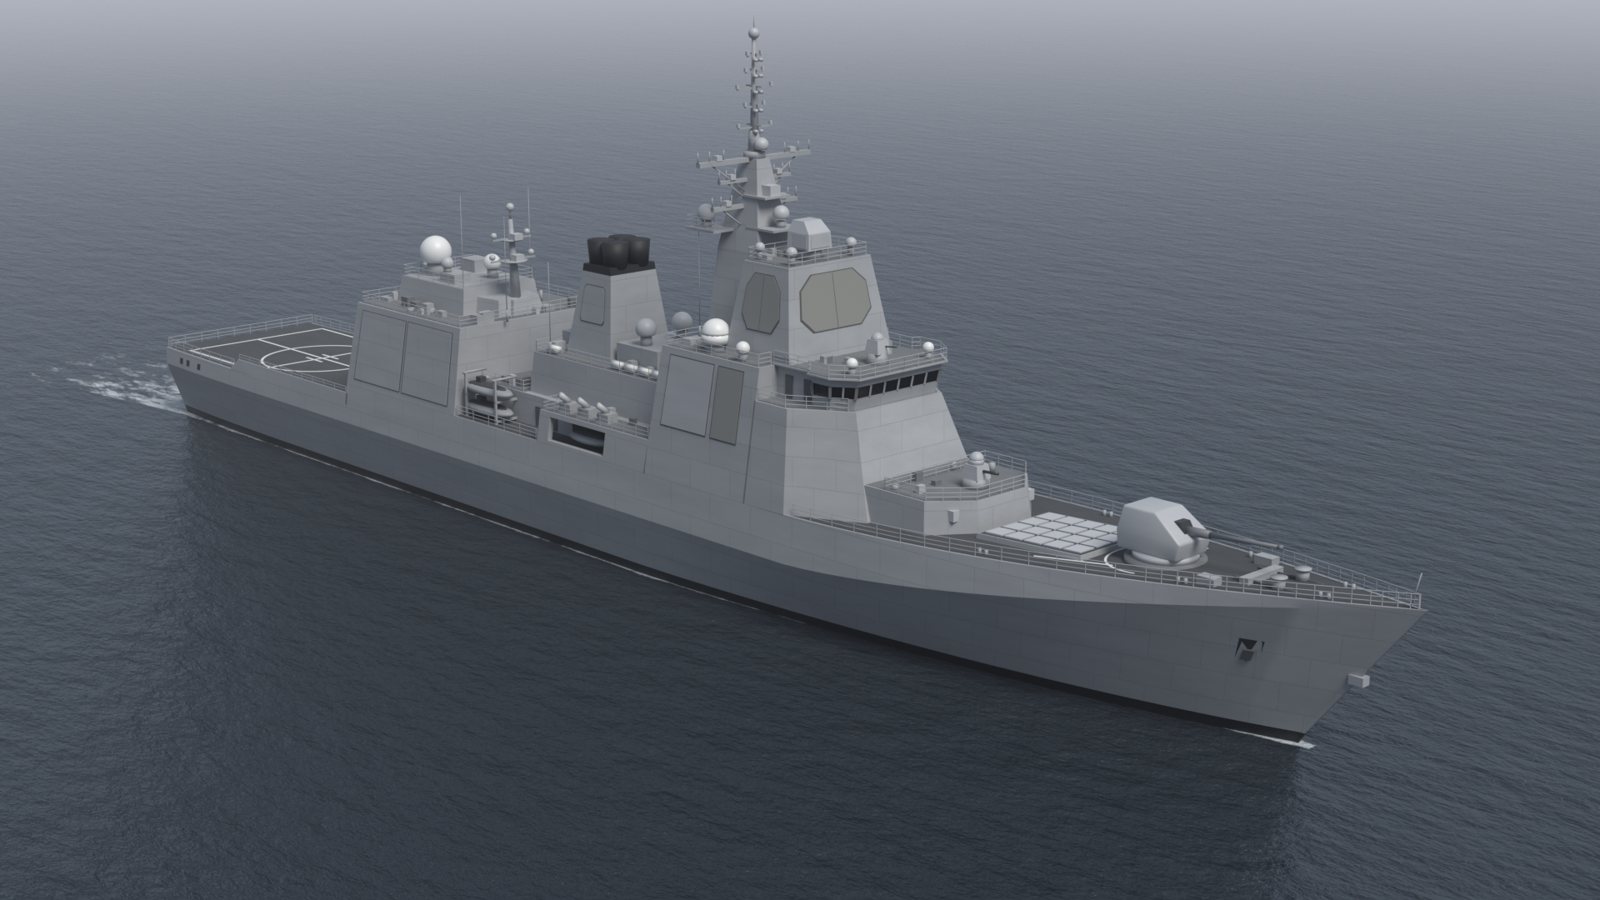
GPT-6 Astra
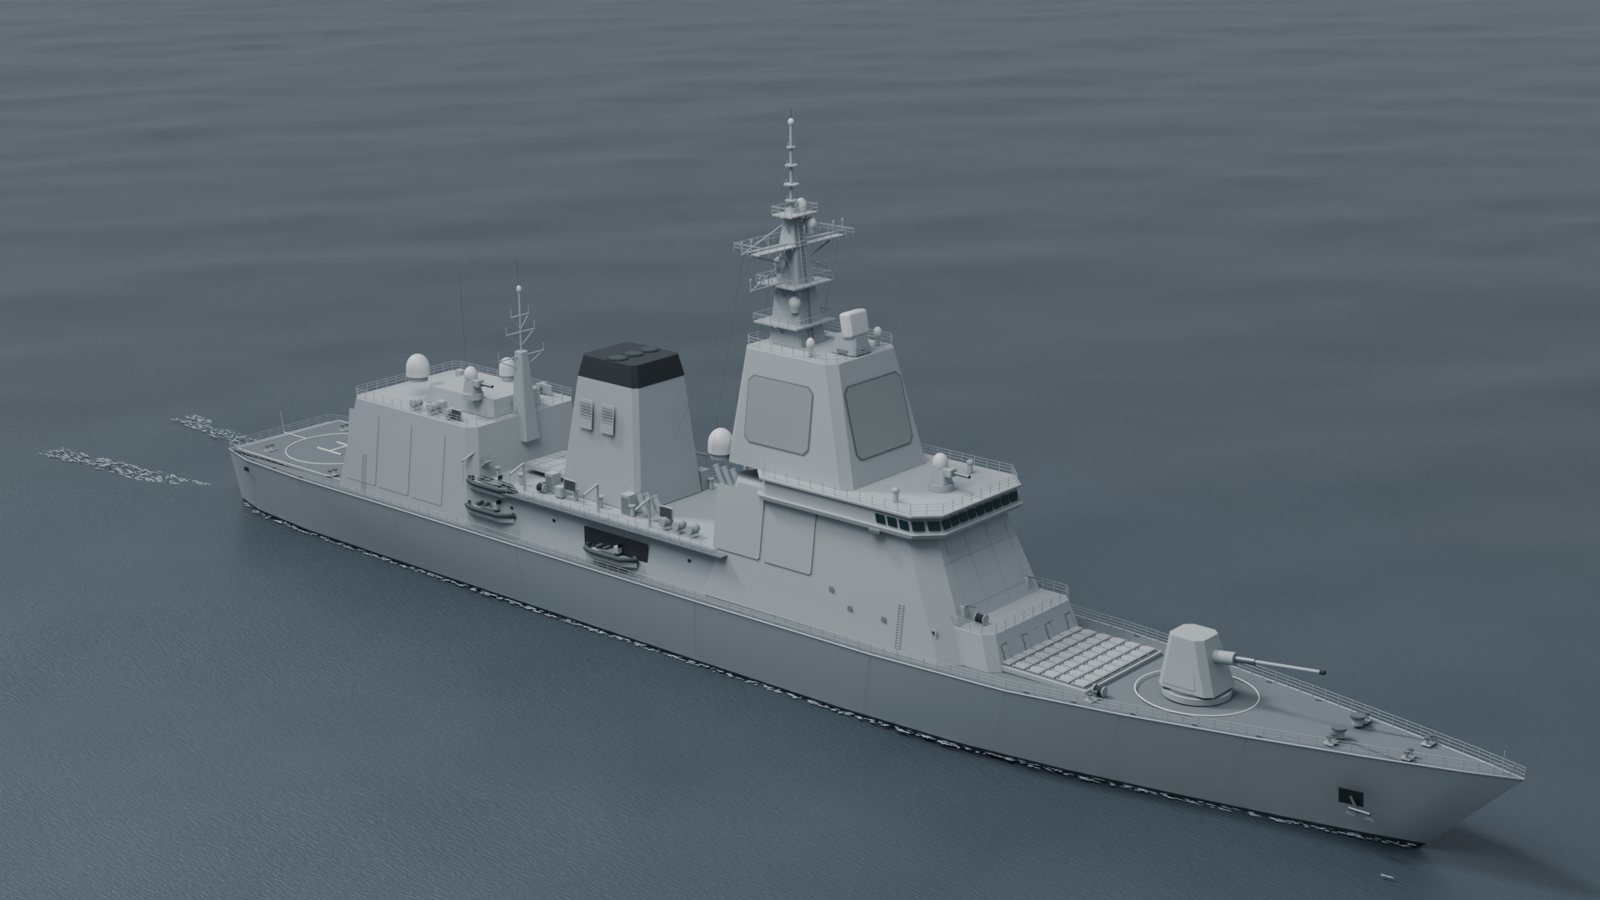
Gemini 4 Argon · Antigravity CLI
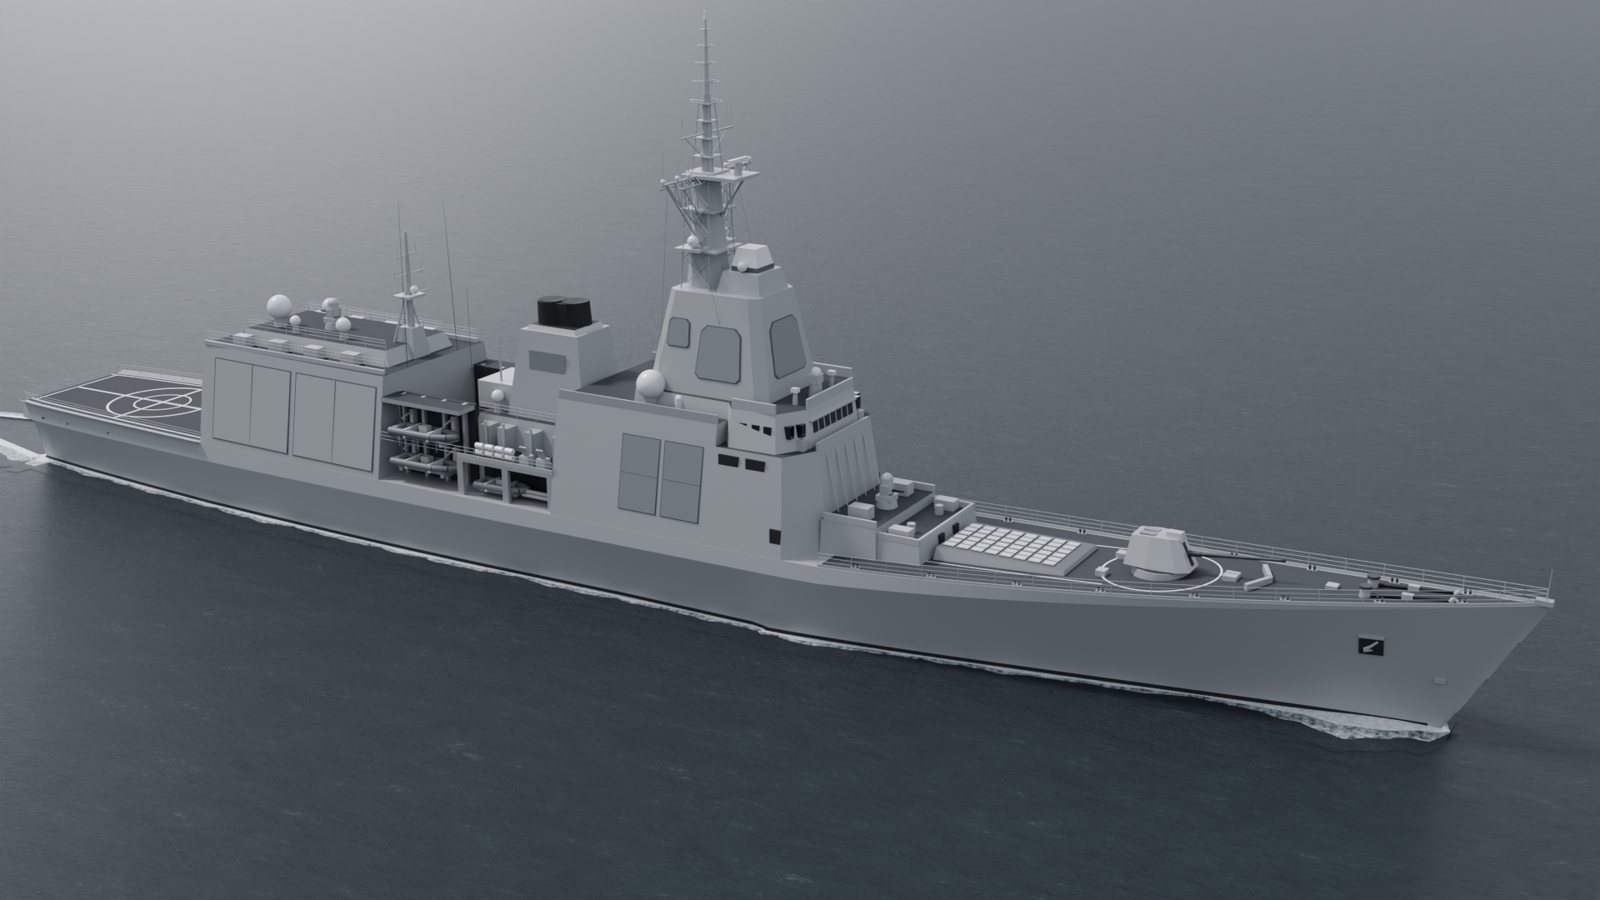
Gemini 4 in Claude Code (first round)
the harness Fable 5.2 ran in; low and medium got stuckGemini 4 Argon · Claude Code · low
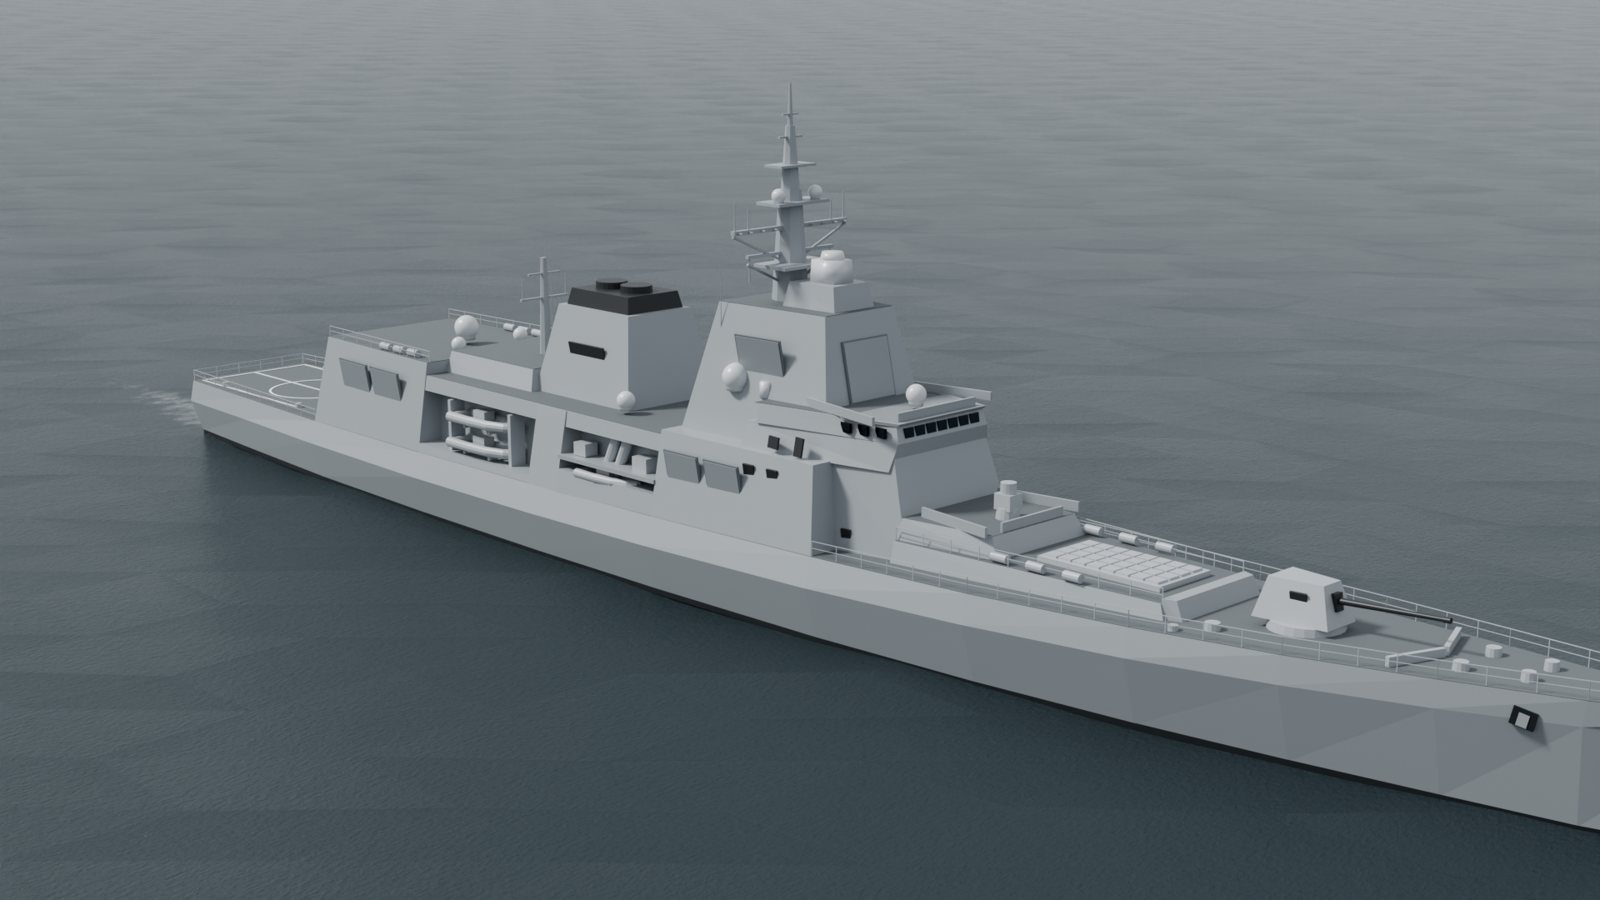
Gemini 4 Argon · Claude Code · medium
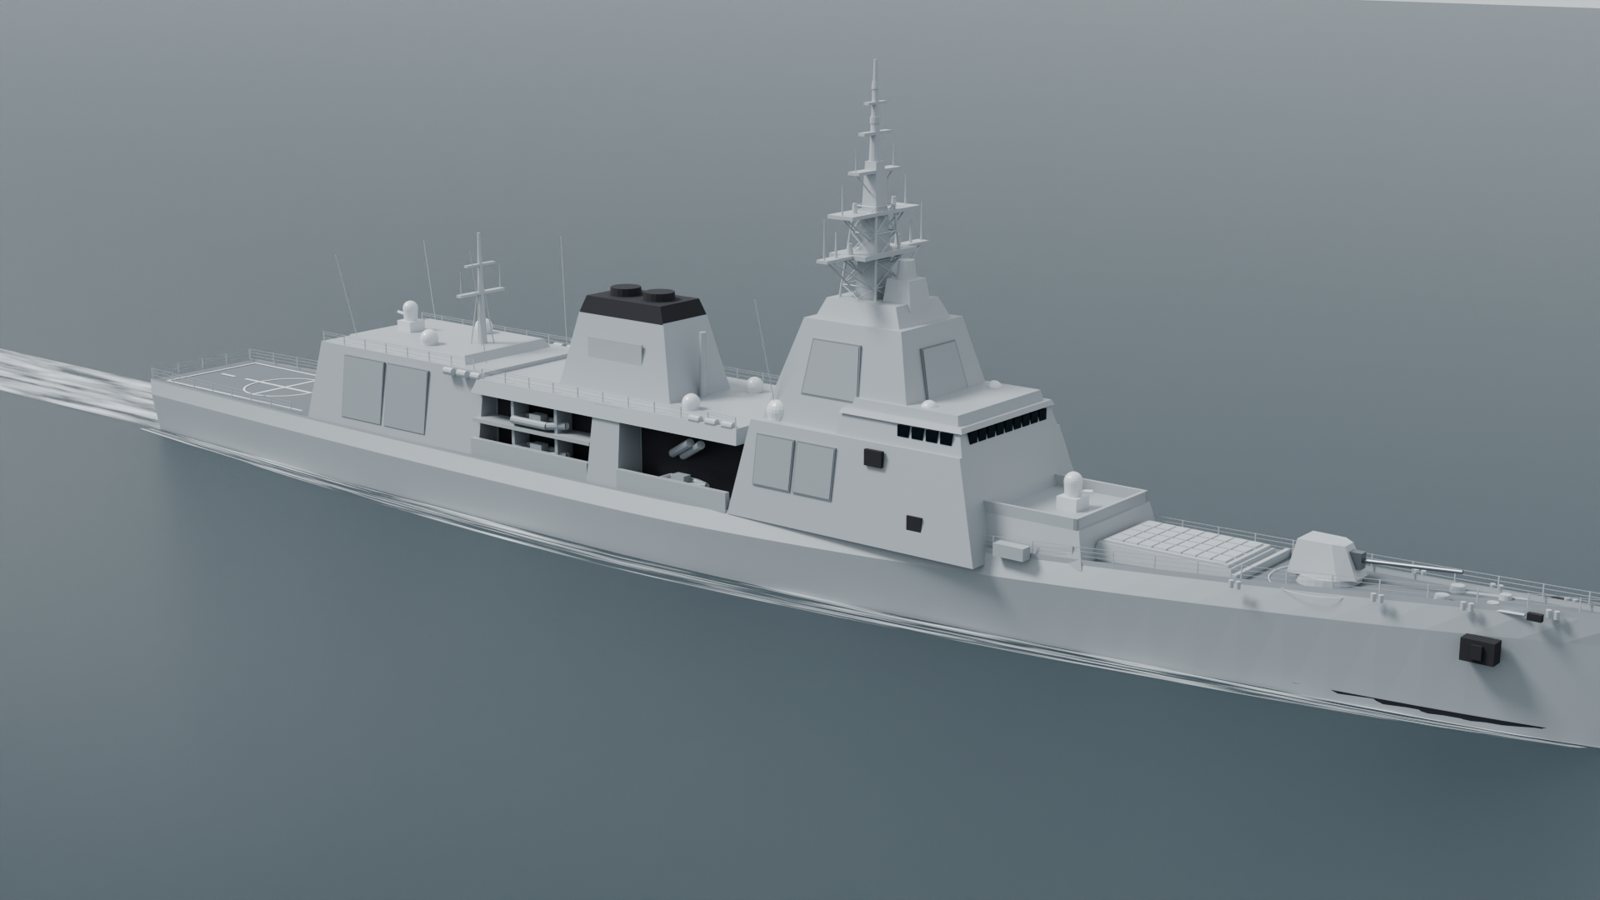
Gemini 4 Argon · Claude Code · high
How we ran it
- Claude Fable 5.2 ran in Claude Code (model claude-fable-5-2) at low, medium and high effort, with clean settings: none of our private instructions, memory or add-on tools, only the prompt and the picture. It had shell access, could run Blender 5.2 headless on a GPU server, and could open its own renders as images.
- The three runs started within a minute of each other on the same GPU server as the October runs, with a 50-minute limit each. Nobody stepped in during a run.
- The GPT-6 Astra and Gemini 4 Argon results are the 14 October runs (Astra in the Codex CLI, Gemini 4 in Claude Code and in Google's Antigravity CLI). They were not rerun today, so models and harnesses may have moved a little since.
- Effort is each model's own reasoning setting (low, medium, high).
- One run per setting. Expect run-to-run variation; treat this as a field note, not a benchmark. Judging the ships is your call: we only measured time, tokens and price.